6 posts tagged with "snapshots"

Topics related to database and acceleration snapshots

View All Tags

Spice v2.4.0-rc.2 (Oct 15, 2026)

Β· 28 min read
Jack Eadie
Member of Technical Staff at Spice AI

Spice v2.4.0-rc.2 is now available! πŸ”₯

Spice v2.4.0-rc.2 is the second release candidate of v2.4.0 for early testing and feedback. It introduces a new OpenAI-compatible POST /v1/decisions API backed by an OpenAI decision model, TypeSafe Jev, or any other LLM in the Spicepod that can answer decisions. Five new SQL functions bring the same AI classification, scoring, and decisions into SQL.

This release also adds Iceberg reads without a catalog and improves acceleration snapshots. Cayenne gains runtime-wide adaptive tuning and applies acceleration configuration changes on restart.

Highlights in this release:

  • AI Decisions API and decisions in SQL: An OpenAI-compatible /v1/decisions API, plus five SQL functions for filtering, classifying, and scoring data with models.
  • Iceberg without a catalog: Read a table directly from its root directory or pin a metadata file to read a fixed version.
  • Shared runtime state: Startup validation and a common location for cluster state, rate control, cache warmup, and acceleration snapshots.
  • SQL results cache: Cache entries expire by TTL and remain available across data refreshes.
  • Cayenne acceleration: Improvements to primary-key loading, secondary indexes, and configuration updates.
  • OpenTelemetry log export: Send runtime logs to any OTLP endpoint as structured log records, and choose which failed queries are logged.

These notes cover changes since v2.4.0-rc.1. Review Breaking Changes before upgrading; upgrades from earlier versions also require the rc.1 migration guidance.

What's New in v2.4.0-rc.2​

AI Decisions API and decisions in SQL​

Spice now supports POST /v1/decisions, which is compatible with the OpenAI Decisions API. A decision request asks typed questions about an input. Each answer comes back with its probabilities and a confidence.

Any model in the Spicepod can answer a decision request:

ModelExample fromProbabilities
OpenAI decision modelopenai:gpt-6-lunaThe estimates of the model.
TypeSafe decision modeltypesafe:jevCalibrated by the model.
Any other LLMopenai:gpt-4o-mini, anthropic:claude-haiku-4-5The estimates of the chat model.

OpenAI decision models use the native OpenAI Decisions API. gpt-6-luna also supports chat and /v1/nsql. TypeSafe Jev returns calibrated probabilities and answers decisions only. Other LLMs answer through chat completions and return their own uncalibrated estimates.

models:
- from: openai:gpt-6-luna
name: luna
params:
openai_api_key: ${secrets:OPENAI_API_KEY}
- from: typesafe:jev
name: jev
params:
typesafe_api_key: ${secrets:TYPESAFE_API_KEY}

Five new SQL functions make the same decisions available in queries:

FunctionResult
ai_if(input, condition)BOOLEAN: true when the probability of "yes" exceeds 0.5.
ai_probability(input, condition)DOUBLE: a probability from 0 to 1.
ai_classify(input, labels)VARCHAR: one of the supplied labels.
ai_score(input, instructions, levels)DOUBLE: a probability-weighted score.
ai_decide(input, questions)STRUCT: answers, probabilities, and confidence for a set of questions.
SELECT
id,
ai_classify(body, ['billing', 'technical', 'account'], model => 'support_model' ) AS team,
ai_probability(body, 'The customer is requesting a refund', model => 'support_model') AS refund_probability
FROM tickets
WHERE status = 'open';

See AI functions for more examples.

Iceberg Without a Catalog​

Read an Iceberg table directly from object storage or the local filesystem, without configuring a catalog. Set from to the table root using file://, s3://, s3a://, gs://, or gcs://:

datasets:
- from: iceberg:s3://my-bucket/warehouse/db/taxis
name: taxis
params:
iceberg_s3_region: us-east-1

Spice resolves the metadata file on each query and refresh. It supports metadata/version-hint.text as well as a fixed version (a path relative to the table root or a full URL):

datasets:
- from: iceberg:s3://my-bucket/warehouse/db/taxis
name: taxis
params:
iceberg_s3_region: us-east-1
iceberg_metadata_path: /metadata/00003-8f2c.metadata.json

Fixed tables are read-only. The earlier metadata_path parameter remains supported with a deprecation warning; see Breaking Changes.

Shared Runtime State​

runtime.state provides a shared, object-store location for cluster state, rate control, SQL results-cache warmup, and acceleration snapshots. Each feature uses its own subdirectory within the provided location.

Acceleration snapshots now default to the snapshots/ subdirectory when runtime.state is configured.

runtime:
state:
location: s3://my-bucket/spice/

datasets:
- from: postgres:orders
name: orders
acceleration:
enabled: true
engine: cayenne
mode: file
snapshots: enabled

A dataset can override the snapshot location, its settings, and the bootstrap behavior on its own acceleration:

datasets:
- from: postgres:events
name: events
acceleration:
snapshots: enabled
snapshots_location: s3://archive-bucket/snapshots/
snapshots_params:
s3_region: eu-west-1
snapshots_bootstrap_on_failure_behavior: fallback

Other changes to shared state:

  • Snapshot queues: An SQS queue that covers the whole runtime.state prefix no longer causes an ERROR log for each scheduler heartbeat. The snapshot reader now deletes messages for the other state folders without a log.

SQL Results Cache​

The SQL results cache now expires entries by TTL, independent of acceleration refreshes, CDC batches, and retention passes no longer invalidate cached results.

Review item_ttl and stale_while_revalidate_ttl when upgrading: a successful refresh no longer makes cached results reflect the refreshed data immediately. See Breaking Changes.

Cayenne Acceleration​

Adaptive tuning is configured once for the runtime. Enable it with runtime.adaptive_tuning and set targets under runtime.params:

runtime:
adaptive_tuning: enabled
params:
target_freshness: 30s

Supported targets are target_replication_lag, target_freshness, target_query_latency, target_convergence_window, and target_qph. Adaptive tuning defaults to disabled. See Breaking Changes and the runtime YAML documentation.

Other Cayenne improvements include:

  • Primary-key loading: Keyed tables build their primary-key filter during the initial load and bulk-load without per-row routing or a whole-table fold.
  • Position deletes: cayenne_deletion_mode: auto can select position deletes for small primary-key tables on local storage on Linux systems with at least eight physical cores.
  • Secondary indexes: Index runs are persisted, indexes remain complete across acceleration snapshots, and CDC maintains indexes for each operation type. Hash joins read each file once when narrowing a scan through an index.
  • Partition handling: Cayenne rejects stored data with an incompatible partition_by, protects keyed appends to partitioned tables during publication, and prepares every partition after a refresh.
  • Storage and query correctness: Cayenne reclaims snapshot directories superseded by a reload, corrects pruning for NaN values, and fixes deletion-index bounds and reload fencing.
  • Snapshot storage growth: A writer with snapshots_trigger: refresh_complete kept one more copy of the table for each refresh. Each snapshot held file deletions, so Cayenne skipped each cleanup pass. Cayenne now runs the cleanup when a snapshot releases its hold. In a 10-minute test with a refresh every 60 seconds, each dataset kept 1 snapshot directory instead of 10.
  • Configuration changes on restart: A change to write settings only, such as cayenne_sort_columns or cayenne_compression_strategy, applies to the existing acceleration. A change to primary_key or partition_by rebuilds the acceleration from the source only under specific conditions. See Cayenne Configuration Updates.

OpenTelemetry Log Export​

Spice can now send its logs to an OpenTelemetry Collector, or any OTLP endpoint, as structured OTLP log records. Logs use the same otel_exporter that already sends metrics. A new runtime.query.log_errors setting chooses which failed queries are logged.

runtime:
telemetry:
otel_exporter:
endpoint: otel-collector:4317
signals: [metrics, logs] # new; default [metrics]
query:
log_errors: execution # new; none (default) | execution | all
  • Structured records: Each log line becomes an OTLP log record with its severity, the message as the body, typed fields as attributes, and the logging module as the instrumentation scope. Records share the resource attributes of exported metrics.
  • Trace correlation: A record logged during a query carries the query's trace ID, the same ID returned in spice-trace-id and stored in runtime.task_history.
  • Delivery: Records are batched on a dedicated export runtime, separate from query and HTTP traffic, and flushed at shutdown so the final error and Goodbye! reach the endpoint. For OTLP/HTTP endpoints, logs are sent to <base>/v1/logs.
  • Cluster executors: Executors export their logs with the scheduler's telemetry settings, including headers resolved from the scheduler's secrets.

runtime.query.log_errors controls which failed queries are logged:

ValueWhat is logged
none (default)Existing behavior: a query refused for memory at WARN, and every other failure at DEBUG
executionAlso queries that failed while running, at WARN
allAlso queries rejected before running (syntax and planning errors), at INFO

Each record reads Query failed: <error>, with error_code and datasets fields and the query's trace ID. The SQL text is never logged.

Unknown-column errors are now reported with the correct error_code instead of InternalError, in logs, runtime.task_history, and the query_failures metric.

See OpenTelemetry Logs Export, Exporting logs, and runtime.query.log_errors.

Fixes and Improvements​

AI APIs and Models​

  • Responses API: /v1/responses executes Spice tools and honors tool_recursion_limit when streaming. It returns Spice tool calls as mcp_call items in output, allowing clients that manage their own conversation history to replay them.
  • Model controls: /v1/nsql accepts reasoning_effort, and rerank() uses evaluation models with a strategy selected for each query.
  • Anthropic: Streaming handles responses that begin with a thinking block, empty text blocks are dropped, and anthropic_workspace_id is available as a model parameter.
  • OpenAI: Models with an unknown service tier can load and serve requests.
  • Luna: gpt-6-luna and its snapshots support chat, /v1/nsql, and native decisions.

Acceleration​

  • Caching point lookups: Lookups on a refresh_mode: caching dataset failed with HTTP 400. This occurred when Cayenne accelerated the dataset, the primary key covered the request columns, and the table held two protected snapshots. The point-lookup plan did not combine the partitions of the Cayenne scan. Lookups now return the cached row or fetch it from the source.

Connectors​

  • MySQL timestamps: Timestamp literals in queries that the runtime sends to MySQL now keep their fractional seconds.

Dependency Updates​

DependencyUpdate
Tursov0.8.2

Breaking Changes​

Shared State Directory Layout and Startup Checks​

State written at the runtime.state root by rc.1 is no longer read from that location. Move existing state objects into the appropriate subdirectories before upgrading to retain them:

StateSubdirectory
Cluster schedulercluster/
Rate controlrate-control/
SQL results-cache warmupresults-cache/

Azure locations (abfs:// and abfss://) need one more step. In rc.1, the runtime ignored the path in an Azure URL and wrote state at the container root. For example, with abfs://container/spice/, rc.1 wrote cluster.json at the container root. This release writes spice/cluster/cluster.json. Move Azure state from the container root into the configured path and then into the feature subdirectory.

An explicit runtime.scheduler.state_location retains its earlier layout. Without migration, Spice starts without the state previously stored at the shared root.

The configured store must accept writes and conditional writes. Spice does not become ready until startup validation succeeds and refuses stores with a newer state format. Check storage permissions and compatibility before upgrading.

SQL Results Cache Freshness​

A refresh no longer invalidates SQL results-cache entries. Queries can return data from before the latest refresh until item_ttl expires, plus stale_while_revalidate_ttl when configured. Reduce item_ttl if results need to follow source refreshes more closely.

Cayenne Tuning Configuration​

Replace the Cayenne tuning parameters with runtime settings that apply across datasets and catalogs:

Previous parameterReplacement
cayenne_tuning: adaptiveruntime.adaptive_tuning: enabled
cayenne_tuning: autoruntime.adaptive_tuning: disabled
cayenne_goal_replication_lagruntime.params.target_replication_lag
cayenne_goal_freshnessruntime.params.target_freshness
cayenne_goal_query_latencyruntime.params.target_query_latency
cayenne_goal_convergence_windowruntime.params.target_convergence_window
cayenne_goal_qphruntime.params.target_qph

runtime.adaptive_tuning accepts only enabled or disabled. Other values, including true, fail the Spicepod load.

Pinned Iceberg Tables​

Replace the deprecated metadata_path parameter with iceberg_metadata_path. The two settings resolve paths differently. metadata_path uses its value as given. iceberg_metadata_path resolves a value without a URL scheme relative to the table root in from. Convert an absolute local path to a full file:// URL or to a path relative to the table root.

Datasets pinned to a .json metadata file are read-only and fail to load with access: read_write. Remove that setting from pinned datasets before upgrading.

Cayenne Configuration Updates​

A restart now applies changed settings to an existing Cayenne acceleration. The result depends on the setting and the dataset:

  • Write settings only: A change to only cayenne_sort_columns, cayenne_cluster_by, cayenne_compression_strategy, cayenne_delta_encoding, or cayenne_shard_key_columns applies to the existing acceleration. Stored rows keep their layout until a refresh or compaction rewrites them.
  • Identity settings: A change to primary_key, partition_by, cayenne_pk_conflict_detection from none to auto, or the data location rebuilds the acceleration from the source. The runtime rebuilds only a dataset with refresh_mode: full, mode: file or file_update, and write_mode: write_through. The source must not be sink:, and must be readable with the schema of the dataset.
  • All other datasets: The acceleration keeps all of its stored settings. This includes write settings that changed in the same restart. The runtime logs a warning that names the change and the fix.

While the runtime cannot read the source, a dataset that qualifies for a rebuild keeps its existing acceleration. A partition_by change or a conflict-detection change cannot use the stored rows, so it fails the dataset instead. Revert the setting, or restart when the source is readable.

A restart alone does not migrate a dataset that does not meet these conditions. Read the startup warning for the dataset before you delete stored data. Allow time for a rebuild when the conditions apply.

Upgrading​

Once release artifacts are available, select v2.4.0-rc.2 explicitly with the CLI, Docker tag, or Helm chart version.

CLI​

spice upgrade v2.4.0-rc.2

Docker​

docker pull spiceai/spiceai:2.4.0-rc.2

See Docker Hub for available tags.

Helm​

helm repo update
helm upgrade spiceai spiceai/spiceai --version 2.4.0-rc.2

Homebrew and AWS Marketplace​

Homebrew and AWS Marketplace follow their published versions. To select this release candidate, use an explicit version through the CLI or Docker.

Spice is also available in the AWS Marketplace.

Contributors​

Changelog​

See the full changelog from v2.4.0-rc.1 to v2.4.0-rc.2.

  • feat(connector-huggingface): Hugging Face datasets data connector (hf://datasets/...) by @lukekim in #14877
  • fix(iceberg): Iceberg REST clients read the real table or get an error, never an empty one by @lukekim in #14588
  • fix(federation): ask the executor for the SELECT 1 placeholder of an empty projection by @krinart in #14851
  • fix(cayenne): float statistics must not leave NaN out of pruning or metadata answers (fixes #14719) by @claudespice in #14792
  • fix: Update tpch benchmark snapshots for accelerated/s3[parquet]-duckdb[file]-2gib.yaml by @github-actions in #14850
  • Update openapi.json by @github-actions in #14858
  • test: strengthen assertions and enforce sign-off coverage by @lukekim in #14740
  • Reapply "fix(sqlite, duckdb): keep a decimal AVG, and on SQLite a decimal SUM, out of the federated plan (fixes #14492)" by @krinart in #14888
  • fix(caching): a GET and a POST to one HTTP path no longer share a cache entry (fixes #14768) by @claudespice in #14884
  • fix(anthropic): drop empty text blocks from assistant messages by @Jeadie in #14834
  • fix(cayenne): ask the table whether it takes a versioned append, instead of predicting it by @lukekim in #14882
  • test(sqlite): guard the Date32 literal cast through the SQLite acceleration's own scan (fixes #14491) by @grokspice in #14703
  • fix(cayenne): read each file once when a hash join narrows an indexed table's scan by @lukekim in #14934
  • fix(sharepoint): list drive items when the listing contains a folder (fixes #2797) by @phillipleblanc in #14946
  • fix(runtime): log each failing dataset's load failure (fixes #14918) by @phillipleblanc in #14939
  • fix(deps): move the DataFusion pin past spiceai/datafusion#256, so FlightSQL Substrait plans read string columns (fixes #14935) by @lukekim in #14944
  • fix(cayenne): publish a keyed partition's append as a protected overlay (fixes #14947) by @lukekim in #14955
  • fix(acceleration): a failed acceleration build no longer keeps the dataset down until restart (fixes #14917) by @phillipleblanc in #14942
  • fix(postgres): reject a changes dataset without a primary key when it loads by @phillipleblanc in #14960
  • feat(spicepod): publish pull request reviews by @lukekim in #14964
  • fix(ci): bound the REPL expect-script waits on silence, not total response time (fixes #13711) by @grokspice in #14963
  • fix(cluster): treat secrets the scheduler declines as not found on executors by @phillipleblanc in #14957
  • fix(flight): return query and data errors as InvalidArgument, not Internal by @phillipleblanc in #14956
  • fix(duckdb,sqlite): correct pushdown for string_agg ORDER BY, concat NULLs, and unsupported fns by @lukekim in #14798
  • fix(ci): provision DuckLake for the ducklake[catalog] schema test, which has never passed by @grokspice in #14952
  • fix(llms): stream Anthropic responses that open with a thinking block (fixes #14909) by @krinart in #14920
  • fix(arrow): serve lookups from enabled indexes; a repeated key disables the index with a warning by @sgrebnov in #14968
  • feat(nsql): accept reasoning_effort on POST /v1/nsql by @lukekim in #14852
  • fix(listing): scan file_extension '*' tables through ListingTable, so Glue joins broadcast again (fixes #14890) by @krinart in #14972
  • fix(llms): load and serve an OpenAI model when a reply names an unknown service tier (fixes #14916) by @krinart in #14927
  • feat(cayenne): always persist secondary index runs by @sgrebnov in #14979
  • fix(cache): expire results-cache entries in insertion order instead of walking every LRU list by @bjchambers in #14919
  • feat: decisions in SQL (ai_if, ai_probability, ai_classify, ai_score, ai_decide) and an OpenAI-compatible /v1/decisions by @lukekim in #14838
  • fix(rrf): keep named arguments on nested search calls by @phillipleblanc in #14975
  • fix(rate-control): hold instances that set different limits for one origin to the lowest (fixes #14913) by @krinart in #14932
  • fix(vortex): keep temporal casts Vortex can't evaluate out of the scan by @sgrebnov in #14985
  • fix(acceleration): recommend mode: file for CDC on_conflict migrations to Cayenne by @bjchambers in #14928
  • test(huggingface): unblock the merge queue: read imdb's parquet conversion through @~parquet and fail fast on a vanished Hub pin by @grokspice in #14998
  • test(cayenne): link the integration tests into one test binary by @bjchambers in #14976
  • test(vortex): compile the integration tests into a binary the sign-off gate runs by @bjchambers in #14987
  • fix(http): reject a request_path that URL parsing would rewrite by @bjchambers in #14965
  • fix(clickhouse): load LowCardinality, DateTime64, Array, Map, Tuple, Enum, 128-bit integer and IP columns by @phillipleblanc in #14953
  • Add anthropic_workspace_id param for Anthropic models by @Jeadie in #14829
  • fix(acceleration): keep retention-evicted rows out of the on_zero_results source fallback by @lukekim in #14783
  • test: run federated source tests on every supported LTS release line by @lukekim in #14936
  • fix(drasi): forward CDC creates and snapshots as upserts by @ewgenius in #14791
  • fix(datafusion-optimizer-rules): answer only plain partition columns from the listing by @lukekim in #14806
  • fix(connector-huggingface): retry Hub API responses that break off part way, and harden the live-Hub check by @lukekim in #15009
  • Improve types methods in runtime-rate-control by @Jeadie in #14573
  • fix(models): /v1/responses runs Spice tools and honors tool_recursion_limit when streaming (fixes #14905, #14631) by @krinart in #14930
  • Update openapi.json by @github-actions in #14908
  • test(cayenne): run the heap-measuring tests in one isolated test binary by @bjchambers in #15010
  • test(vortex): run vortex-datafusion's integration tests in the sign-off gate by @bjchambers in #15001
  • fix(cayenne): refuse acceleration data stored under a different partition_by by @phillipleblanc in #15019
  • Update openapi.json by @github-actions in #15018
  • fix(ci): keep the OpenAPI regeneration PR current instead of skipping while one is open by @phillipleblanc in #15023
  • fix: Cayenne deletion-index bounds and reload fencing, scan-statistics single-flight, UDF filter pushdown, Server-Timing, results-cache determinism, and view loading by @lukekim in #14993
  • fix(cayenne): load write-back without on_conflict, and refuse pk_conflict_detection: none where it loses data (fixes #14886, #14889) by @bjchambers in #14891
  • chore: Update Turso crate to 0.8.2 by @spiceemma in #15022
  • feat(cayenne): runtime-wide adaptive_tuning and target_* settings by @peasee in #14844
  • ci: apply whole-binary nextest overrides to the module test sets they select by @bjchambers in #15011
  • fix(snapshots): give each snapshot publish its own object name, so publishes in the same second stop overwriting each other by @phillipleblanc in #15028
  • test(data_components): compile the integration tests into one test binary by @bjchambers in #14991
  • fix(glue): load Iceberg tables from S3 buckets with dots in the name by @phillipleblanc in #15053
  • fix(runtime): give each runtime.state feature its own folder by @phillipleblanc in #15036
  • test(data_components): make the HTTP provider snapshots independent of the machine by @bjchambers in #15000
  • fix(json): reject incomplete arrays and avoid repeated parsing by @phillipleblanc in #15054
  • test(runtime): drive the cdc_cayenne tests through Cayenne's change sink by @bjchambers in #15003
  • ci(object_store_occ): run the WAL E2E suite on self-hosted runners against disk, MinIO, RustFS and spiceio by @lukekim in #15031
  • test(llms): compile the credential-free tests into the integration binary by @bjchambers in #14990
  • fix(cayenne): keep secondary indexes complete across acceleration snapshots by @sgrebnov in #15068
  • ci(setup-minio): name the missing secret instead of failing in mc's argument parser by @grokspice in #15073
  • ci: run Substrait Mode B on the Linux runners that can reach the trunk spiced builds by @grokspice in #15074
  • feat(rerank): use evaluation models (TypeSafe) in rerank(), with per-query strategy by @Jeadie in #14782
  • build(deps): bump the github-actions-dependencies group across 5 directories with 7 updates by @dependabot in #15027
  • fix(cayenne): reclaim the snapshot directories a snapshot reader's reload supersedes by @sgrebnov in #15069
  • feat(iceberg): read a table from a pinned metadata file without a catalog by @sgrebnov in #15081
  • Fixes for MCP server by @Jeadie in #15041
  • fix(search): vector_search returns its top k rows by score on chunked and multi-vector columns (fixes #14819) by @claudespice in #15056
  • fix(postgres): keep applying CDC changes after a source column type change, and never store a rounded value (refs #14718) by @claudespice in #15037
  • perf(iceberg): decode Iceberg scans at the session batch_size by @bjchambers in #15072
  • fix(rate-control): admit waiting requests in arrival order at the charge in force (fixes #14912) by @krinart in #14931
  • fix(rate-control): compare shared-origin settings as they resolve (fixes #14914) by @krinart in #14937
  • fix(decisions): Fixes for /v1/decisions by @Jeadie in #15040
  • perf(cayenne): bulk-load a keyed table without per-row routing or a whole-table fold by @bjchambers in #15076
  • fix(cayenne): list a new snapshot's files once, when it is published by @bjchambers in #15077
  • test(runtime,spiced): compile integration tests into declared binaries, run the ones no CI job ran, and remove the uncalled supersede_initial_load by @bjchambers in #15005
  • fix(duckdb): unparse string literals with backslash-quote exactly by @lukekim in #15083
  • ci(e2e): don't run rust-cache on the macOS build, whose save deletes cargo from sibling runners by @grokspice in #15100
  • feat(testoperator): record per-query search metrics by @Jeadie in #15090
  • fix(vortex): keep casts Vortex cannot evaluate out of the scan by @phillipleblanc in #15096
  • feat(index): operation-aware CDC index maintenance via IndexChangeSet by @Jeadie in #14340
  • ci: run merge-queue Mode A TPC-H and LLM integration tests on spiceai-macos-large by @lukekim in #15116
  • docs(cayenne): the per-file fold merges no source files, but may roll by @bjchambers in #15101
  • build(deps): bump async-openai to the fork's merge of upstream main by @krinart in #14980
  • feat(iceberg): read a table root without a catalog, finding its current metadata on every query by @sgrebnov in #15095
  • fix(runtime): fail recovery of an unsaved running query by @phillipleblanc in #15092
  • perf(cayenne): build a keyed table's primary-key filter during its first load by @phillipleblanc in #15099
  • test(cayenne): guard per-file statistics sharing for listings outside a scan view by @bjchambers in #15103
  • feat(cache): age SQL results on TTL instead of invalidating them on refresh by @bjchambers in #15033
  • fix(deps): estimate selective IN lists and OR-of-equalities from NDV by @bjchambers in #14140
  • Change codeql runner from spiceai-macos to spiceai-macos-large by @lukekim in #15120
  • fix(flightsql): prepared-statement GetFlightInfo schema matches the stream when parameters are bound by @lukekim in #15106
  • fix(telemetry): report the configured CPU count as host.cpu.count by @lukekim in #15108
  • fix(runtime-table): prepare every partition of a partitioned Cayenne table after a refresh by @bjchambers in #15111
  • fix: Update Search integration test snapshots by @github-actions in #15050
  • test(iceberg): read the Glue fixture unpinned and check the picked metadata file by @sgrebnov in #15115
  • test(cayenne): differential and plan coverage for secondary indexes on partitioned accelerations by @bjchambers in #15113
  • test: answer results-cache misses from the acceleration while the source is down by @bjchambers in #15112
  • ci(lint): fail on test files no target compiles, and document the integration test layout by @bjchambers in #15109
  • feat(snapshots): store snapshots under runtime.state, built by the shared state-location builder by @sgrebnov in #15117
  • fix(federation): match NULL rows in pushed-down INTERSECT and EXCEPT (fixes #14941) by @sgrebnov in #15110
  • fix(models): allowed_tools shape, provider error statuses, decision response model (fixes #14910) by @krinart in #14977
  • feat(cayenne): let deletion_mode auto pick position deletes for small primary-key tables by @lukekim in #15042
  • fix(iceberg): keep nested child namespaces when loading an Iceberg catalog by @lukekim in #15105
  • fix(flight): authenticate before binding sessions, and bound TLS handshakes by @phillipleblanc in #15128
  • fix(test): wait for pkd_ctl to load before reading its bootstrap row in the write-back pk_conflict test by @grokspice in #15102
  • fix(models): return Spice tool calls in /v1/responses output so clients can replay them by @krinart in #15126
  • test(mysql): skip the SQL results cache in the binlog replication end-to-end tests by @grokspice in #15141
  • feat(runtime): check runtime.state at startup, and record its state format by @phillipleblanc in #15138
  • feat(acceleration): apply changed acceleration settings on restart by @lukekim in #15094
  • fix(models): enable Luna chat and NSQL support by @krinart in #15166
  • fix(acceleration): read every accelerator partition in a caching point lookup by @phillipleblanc in #15177
  • fix(cayenne): run snapshot-directory sweeps when a snapshot releases its file-deletion hold by @sgrebnov in #15179
  • feat(telemetry): export runtime logs over OTLP and log failed queries by level by @lukekim in #15176

Spice v1.11.0 (Jan 28, 2026)

Β· 58 min read
William Croxson
Member of Technical Staff at Spice AI

Announcing the release of Spice v1.11.0-stable! ⚑

In Spice v1.11.0, Spice Cayenne reaches Beta status with acceleration snapshots, Key-based deletion vectors, and Amazon S3 Express One Zone support. DataFusion has been upgraded to v51 along with Arrow v57.2, and iceberg-rust v0.8.0. v1.11 adds several DynamoDB & DynamoDB Streams improvements such as JSON nesting, and adds significant improvements to Distributed Query with active-active schedulers and mTLS for enterprise-grade high-availability and secure cluster communication.

This release also adds new SMB, NFS, and ScyllaDB Data Connectors (Alpha), Prepared Statements with full SDK support (gospice, spice-rs, spice-dotnet, spice-java, spice.js, and spicepy), Google LLM Support for expanded AI inference capabilities, and significant improvements to caching, observability, and Hash Indexing for Arrow Acceleration.

What's New in v1.11.0​

Spice Cayenne Accelerator Reaches Beta​

Spice Cayenne has been promoted to Beta status with acceleration snapshots support and numerous performance and stability improvements.

Key Enhancements:

  • Key-based Deletion Vectors: Improved deletion vector support using key-based lookups for more efficient data management and faster delete operations. Key-based deletion vectors are more memory-efficient than positional vectors for sparse deletions.
  • S3 Express One Zone Support: Store Cayenne data files in S3 Express One Zone for single-digit millisecond latency, ideal for latency-sensitive query workloads that require persistence.

Improved Reliability:

  • Resolved FuturesUnordered reentrant drop crashes
  • Fixed memory growth issues related to Vortex metrics allocation
  • Metadata catalog now properly respects cayenne_file_path location
  • Added warnings for unparseable configuration values

For more details, refer to the Cayenne Documentation.

DataFusion v51 Upgrade​

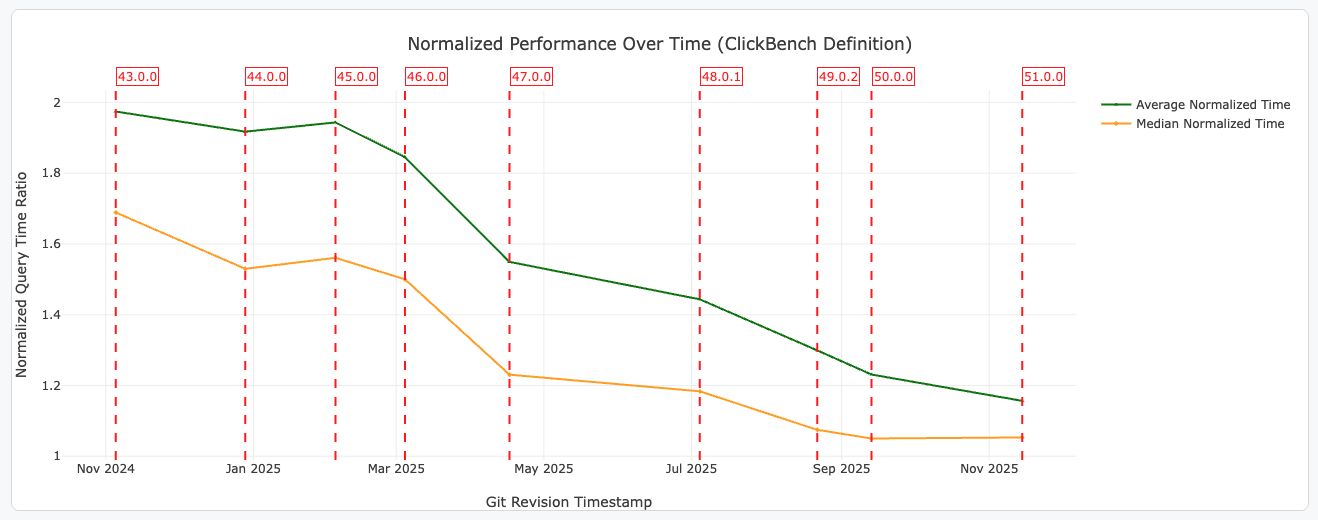
Apache DataFusion has been upgraded to v51, bringing significant performance improvements, new SQL features, and enhanced observability.

DataFusion v51 ClickBench Performance

Performance Improvements:

  • Faster CASE Expression Evaluation: Expressions now short-circuit earlier, reuse partial results, and avoid unnecessary scattering, speeding up common ETL patterns
  • Better Defaults for Remote Parquet Reads: DataFusion now fetches the last 512KB of Parquet files by default, typically avoiding 2 I/O requests per file
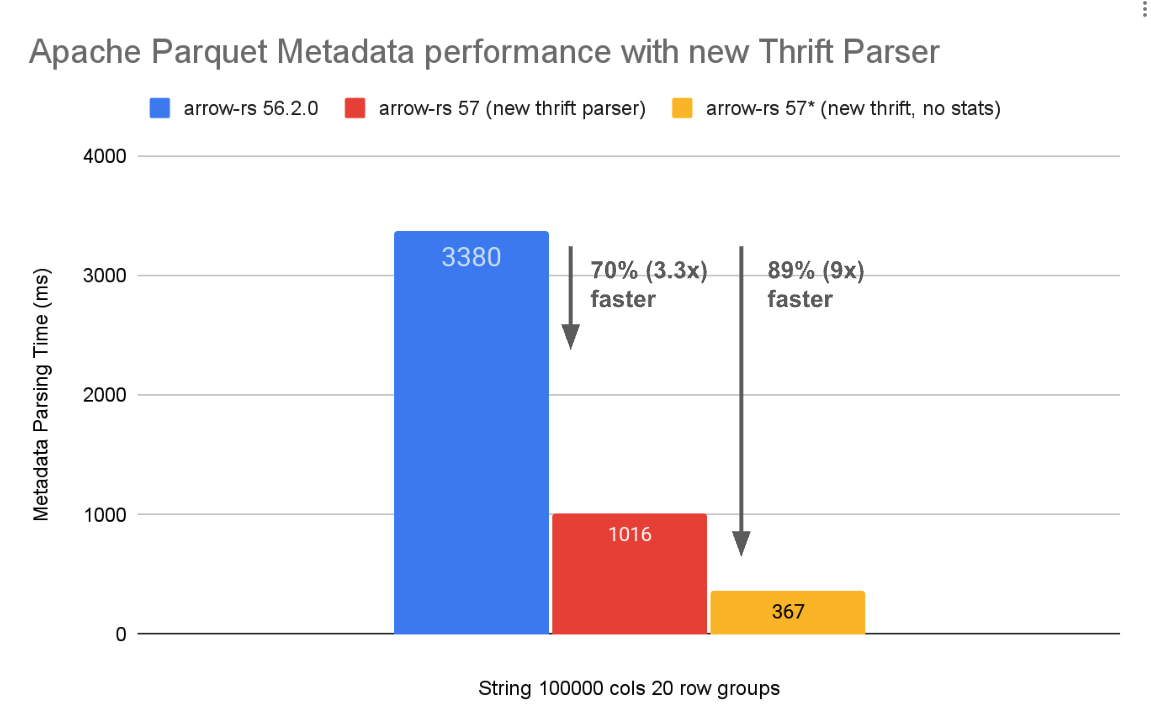
  • Faster Parquet Metadata Parsing: Leverages Arrow 57's new thrift metadata parser for up to 4x faster metadata parsing

New SQL Features:

  • SQL Pipe Operators: Support for |> syntax for inline transforms
  • DESCRIBE <query>: Returns the schema of any query without executing it
  • Named Arguments in SQL Functions: PostgreSQL-style param => value syntax for scalar, aggregate, and window functions
  • Decimal32/Decimal64 Support: New Arrow types supported including aggregations like SUM, AVG, and MIN/MAX

Example pipe operator:

SELECT * FROM t
|> WHERE a > 10
|> ORDER BY b
|> LIMIT 5;

Improved Observability:

  • Improved EXPLAIN ANALYZE Metrics: New metrics including output_bytes, selectivity for filters, reduction_factor for aggregates, and detailed timing breakdowns

Arrow 57.2 Upgrade​

Apache Arrow has been upgraded to v57.2, bringing major performance improvements and new capabilities.

Arrow 57 Parquet Metadata Parsing Performance

Key Features:

  • 4x Faster Parquet Metadata Parsing: A rewritten thrift metadata parser delivers up to 4x faster metadata parsing, especially beneficial for low-latency use cases and files with large amounts of metadata
  • Parquet Variant Support: Experimental support for reading and writing the new Parquet Variant type for semi-structured data, including shredded variant values
  • Parquet Geometry Support: Read and write support for Parquet Geometry types (GEOMETRY and GEOGRAPHY) with GeospatialStatistics
  • New arrow-avro Crate: Efficient conversion between Apache Avro and Arrow RecordBatches with projection pushdown and vectorized execution support

DynamoDB Connector Enhancements​

  • Added JSON nesting for DynamoDB Streams
  • Improved batch deletion handling

Distributed Query Improvements​

High Availability Clusters: Spice now supports running multiple active schedulers in an active/active configuration for production deployments. This eliminates the scheduler as a single point of failure and enables graceful handling of node failures.

  • Multiple schedulers run simultaneously, each capable of accepting queries
  • Schedulers coordinate via a shared S3-compatible object store
  • Executors discover all schedulers automatically
  • A load balancer distributes client queries across schedulers

Example HA configuration:

runtime:
scheduler:
state_location: s3://my-bucket/spice-cluster
params:
region: us-east-1

mTLS Verification: Cluster communication between scheduler and executors now supports mutual TLS verification for enhanced security.

Credential Propagation: S3, ABFS, and GCS credentials are now automatically propagated to executors in cluster mode, enabling access to cloud storage across the distributed query cluster.

Improved Resilience:

  • Exponential backoff for scheduler disconnection recovery
  • Increased gRPC message size limit from 16MB to 100MB for large query plans
  • HTTP health endpoint for cluster executors
  • Automatic executor role inference when --scheduler-address is provided

For more details, refer to the Distributed Query Documentation.

iceberg-rust v0.8.0 Upgrade​

Spice has been upgraded to iceberg-rust v0.8.0, bringing improved Iceberg table support.

Key Features:

  • V3 Metadata Support: Full support for Iceberg V3 table metadata format
  • INSERT INTO Partitioned Tables: DataFusion integration now supports inserting data into partitioned Iceberg tables
  • Improved Delete File Handling: Better support for position and equality delete files, including shared delete file loading and caching
  • SQL Catalog Updates: Implement update_table and register_table for SQL catalog
  • S3 Tables Catalog: Implement update_table for S3 Tables catalog
  • Enhanced Arrow Integration: Convert Arrow schema to Iceberg schema with auto-assigned field IDs, _file column support, and Date32 type support

Acceleration Snapshots​

Acceleration snapshots enable point-in-time recovery and data versioning for accelerated datasets. Snapshots capture the state of accelerated data at specific points, allowing for fast bootstrap recovery and rollback capabilities.

Key Features:

  • Flexible Triggers: Configure when snapshots are created based on time intervals or stream batch counts
  • Automatic Compaction: Reduce storage overhead by compacting older snapshots (DuckDB only)
  • Bootstrap Integration: Snapshots can reset cache expiry on load for seamless recovery (DuckDB with Caching refresh mode)
  • Smart Creation Policies: Only create snapshots when data has actually changed

Example configuration:

datasets:
- from: s3://my-bucket/data.parquet
name: my_dataset
acceleration:
enabled: true
engine: cayenne
mode: file
snapshots: enabled
snapshots_trigger: time_interval
snapshots_trigger_threshold: 1h
snapshots_creation_policy: on_changed

Snapshots API and CLI: New API endpoints and CLI commands for managing snapshots programmatically.

CLI Commands:

# List all snapshots for a dataset
spice acceleration snapshots taxi_trips

# Get details of a specific snapshot
spice acceleration snapshot taxi_trips 3

# Set the current snapshot for rollback (requires runtime restart)
spice acceleration set-snapshot taxi_trips 2

HTTP API Endpoints:

MethodEndpointDescription
GET/v1/datasets/{dataset}/acceleration/snapshotsList all snapshots for a dataset
GET/v1/datasets/{dataset}/acceleration/snapshots/{id}Get details of a specific snapshot
POST/v1/datasets/{dataset}/acceleration/snapshots/currentSet the current snapshot for rollback

For more details, refer to the Acceleration Snapshots Documentation.

Caching Acceleration Mode Improvements​

The Caching Acceleration Mode introduced in v1.10.0 has received significant performance optimizations and reliability fixes in this release.

Performance Optimizations:

  • Non-blocking Cache Writes: Cache misses no longer block query responses. Data is written to the cache asynchronously after the query returns, reducing query latency for cache miss scenarios.
  • Batch Cache Writes: Multiple cache entries are now written in batches rather than individually, significantly improving write throughput for high-volume cache operations.

Reliability Fixes:

  • Correct SWR Refresh Behavior: The stale-while-revalidate (SWR) pattern now correctly refreshes only the specific entries that were accessed instead of refreshing all stale rows in the dataset. This prevents unnecessary source queries and reduces load on upstream data sources.
  • Deduplicated Refresh Requests: Fixed an issue where JSON array responses could trigger multiple redundant refresh operations. Refresh requests are now properly deduplicated.
  • Fixed Cache Hit Detection: Resolved an issue where queries that didn't include fetched_at in their projection would always result in cache misses, even when cached data was available.
  • Unfiltered Query Optimization: SELECT * queries without filters now return cached data directly without unnecessary filtering overhead.

For more details, refer to the Caching Acceleration Mode Documentation.

Prepared Statements​

Improved Query Performance and Security: Spice now supports prepared statements, enabling parameterized queries that improve both performance through query plan caching and security by preventing SQL injection attacks.

Key Features:

  • Query Plan Caching: Prepared statements cache query plans, reducing planning overhead for repeated queries
  • SQL Injection Prevention: Parameters are safely bound, preventing SQL injection vulnerabilities
  • Arrow Flight SQL Support: Full prepared statement support via Arrow Flight SQL protocol

SDK Support:

SDKSupportMin VersionMethod
gospice (Go)βœ… Fullv8.0.0+SqlWithParams() with typed constructors (Int32Param, StringParam, TimestampParam, etc.)
spice-rs (Rust)βœ… Fullv3.0.0+query_with_params() with RecordBatch parameters
spice-dotnet (.NET)βœ… Fullv0.3.0+QueryWithParams() with typed parameter builders
spice-java (Java)βœ… Fullv0.5.0+queryWithParams() with typed Param constructors (Param.int64(), Param.string(), etc.)
spice.js (JavaScript)βœ… Fullv3.1.0+query() with parameterized query support
spicepy (Python)βœ… Fullv3.1.0+query() with parameterized query support

Example (Go):

import "github.com/spiceai/gospice/v8"

client, _ := spice.NewClient()
defer client.Close()

// Parameterized query with typed parameters
results, _ := client.SqlWithParams(ctx,
"SELECT * FROM products WHERE price > $1 AND category = $2",
spice.Float64Param(10.0),
spice.StringParam("electronics"),
)

Example (Java):

import ai.spice.SpiceClient;
import ai.spice.Param;
import org.apache.arrow.adbc.core.ArrowReader;

try (SpiceClient client = new SpiceClient()) {
// With automatic type inference
ArrowReader reader = client.queryWithParams(
"SELECT * FROM products WHERE price > $1 AND category = $2",
10.0, "electronics");

// With explicit typed parameters
ArrowReader reader = client.queryWithParams(
"SELECT * FROM products WHERE price > $1 AND category = $2",
Param.float64(10.0),
Param.string("electronics"));
}

For more details, refer to the Parameterized Queries Documentation.

Spice Java SDK v0.5.0​

Parameterized Query Support for Java: The Spice Java SDK v0.5.0 introduces parameterized queries using ADBC (Arrow Database Connectivity), providing a safer and more efficient way to execute queries with dynamic parameters.

Key Features:

  • SQL Injection Prevention: Parameters are safely bound, preventing SQL injection vulnerabilities
  • Automatic Type Inference: Java types are automatically mapped to Arrow types (e.g., double β†’ Float64, String β†’ Utf8)
  • Explicit Type Control: Use the new Param class with typed factory methods (Param.int64(), Param.string(), Param.decimal128(), etc.) for precise control over Arrow types
  • Updated Dependencies: Apache Arrow Flight SQL upgraded to 18.3.0, plus new ADBC driver support

Example:

import ai.spice.SpiceClient;
import ai.spice.Param;

try (SpiceClient client = new SpiceClient()) {
// With automatic type inference
ArrowReader reader = client.queryWithParams(
"SELECT * FROM taxi_trips WHERE trip_distance > $1 LIMIT 10",
5.0);

// With explicit typed parameters for precise control
ArrowReader reader = client.queryWithParams(
"SELECT * FROM orders WHERE order_id = $1 AND amount >= $2",
Param.int64(12345),
Param.decimal128(new BigDecimal("99.99"), 10, 2));
}

Maven:

<dependency>
<groupId>ai.spice</groupId>
<artifactId>spiceai</artifactId>
<version>0.5.0</version>
</dependency>

For more details, refer to the Spice Java SDK Repository.

Google LLM Support​

Expanded AI Provider Support: Spice now supports Google embedding and chat models via the Google AI provider, expanding the available LLM options for AI inference workloads alongside existing providers like OpenAI, Anthropic, and AWS Bedrock.

Key Features:

  • Google Chat Models: Access Google's Gemini models for chat completions
  • Google Embeddings: Generate embeddings using Google's text embedding models
  • Unified API: Use the same OpenAI-compatible API endpoints for all LLM providers

Example spicepod.yaml configuration:

models:
- from: google:gemini-2.0-flash
name: gemini
params:
google_api_key: ${secrets:GOOGLE_API_KEY}

embeddings:
- from: google:text-embedding-004
name: google_embeddings
params:
google_api_key: ${secrets:GOOGLE_API_KEY}

For more details, refer to the Google LLM Documentation (see docs PR #1286).

URL Tables​

Query data sources directly via URL in SQL without prior dataset registration. Supports S3, Azure Blob Storage, and HTTP/HTTPS URLs with automatic format detection and partition inference.

Supported Patterns:

  • Single files: SELECT * FROM 's3://bucket/data.parquet'
  • Directories/prefixes: SELECT * FROM 's3://bucket/data/'
  • Glob patterns: SELECT * FROM 's3://bucket/year=*/month=*/data.parquet'

Key Features:

  • Automatic file format detection (Parquet, CSV, JSON, etc.)
  • Hive-style partition inference with filter pushdown
  • Schema inference from files
  • Works with both SQL and DataFrame APIs

Example with hive partitioning:

-- Partitions are automatically inferred from paths
SELECT * FROM 's3://bucket/data/' WHERE year = '2024' AND month = '01'

Enable via spicepod.yml:

runtime:
params:
url_tables: enabled

Cluster Mode Async Query APIs (experimental)​

New asynchronous query APIs for long-running queries in cluster mode:

  • /v1/queries endpoint: Submit queries and retrieve results asynchronously

OpenTelemetry Improvements​

Unified Telemetry Endpoint: OTel metrics ingestion has been consolidated to the Flight port (50051), simplifying deployment by removing the separate OTel port (50052). The push-based metrics exporter continues to support integration with OpenTelemetry collectors.

Note: This is a breaking change. Update your configurations if you were using the dedicated OTel port 50052. Internal cluster communication now uses port 50052 exclusively.

Observability Improvements​

Enhanced Dashboards: Updated Grafana and Datadog example dashboards with:

  • Snapshot monitoring widgets
  • Improved accelerated datasets section
  • Renamed ingestion lag charts for clarity

Additional Histogram Buckets: Added more buckets to histogram metrics for better latency distribution visibility.

For more details, refer to the Monitoring Documentation.

Hash Indexing for Arrow Acceleration (experimental)​

Arrow-based accelerations now support hash indexing for faster point lookups on equality predicates. Hash indexes provide O(1) average-case lookup performance for columns with high cardinality.

Features:

  • Primary key hash index support
  • Secondary index support for non-primary key columns
  • Composite key support with proper null value handling

Example configuration:

datasets:
- from: postgres:users
name: users
acceleration:
enabled: true
engine: arrow
primary_key: user_id
indexes:
'(tenant_id, user_id)': unique # Composite hash index

For more details, refer to the Hash Index Documentation.

SMB and NFS Data Connectors​

Network-Attached Storage Connectors: New data connectors for SMB (Server Message Block) and NFS (Network File System) protocols enable direct federated queries against network-attached storage without requiring data movement to cloud object stores.

Key Features:

  • SMB Protocol Support: Connect to Windows file shares and Samba servers with authentication support
  • NFS Protocol Support: Connect to Unix/Linux NFS exports for direct data access
  • Federated Queries: Query Parquet, CSV, JSON, and other file formats directly from network storage with full SQL support
  • Acceleration Support: Accelerate data from SMB/NFS sources using DuckDB, Spice Cayenne, or other accelerators

Example spicepod.yaml configuration:

datasets:
# SMB share
- from: smb://fileserver/share/data.parquet
name: smb_data
params:
smb_username: ${secrets:SMB_USER}
smb_password: ${secrets:SMB_PASS}

# NFS export
- from: nfs://nfsserver/export/data.parquet
name: nfs_data

For more details, refer to the Data Connectors Documentation.

ScyllaDB Data Connector​

A new data connector for ScyllaDB, the high-performance NoSQL database compatible with Apache Cassandra. Query ScyllaDB tables directly or accelerate them for faster analytics.

Example configuration:

datasets:
- from: scylladb:my_keyspace.my_table
name: scylla_data
acceleration:
enabled: true
engine: duckdb

For more details, refer to the ScyllaDB Data Connector Documentation.

Flight SQL TLS Connection Fixes​

TLS Connection Support: Fixed TLS connection issues when using grpc+tls:// scheme with Flight SQL endpoints. Added support for custom CA certificate files via the new flightsql_tls_ca_certificate_file parameter.

Developer Experience Improvements​

  • Turso v0.3.2 Upgrade: Upgraded Turso accelerator for improved performance and reliability
  • Rust 1.91 Upgrade: Updated to Rust 1.91 for latest language features and performance improvements
  • Spice Cloud CLI: Added spice cloud CLI commands for cloud deployment management
  • Improved Spicepod Schema: Improved JSON schema generation for better IDE support and validation
  • Acceleration Snapshots: Added configurable snapshots_create_interval for periodic acceleration snapshots independent of refresh cycles
  • Tiered Caching with Localpod: The Localpod connector now supports caching refresh mode, enabling multi-layer acceleration where a persistent cache feeds a fast in-memory cache
  • GitHub Data Connector: Added workflows and workflow runs support for GitHub repositories
  • NDJSON/LDJSON Support: Added support for Newline Delimited JSON and Line Delimited JSON file formats

Additional Improvements & Bug Fixes​

  • Model Listing: New functionality to list available models across multiple AI providers
  • DuckDB Partitioned Tables: Primary key constraints now supported in partitioned DuckDB table mode
  • Post-refresh Sorting: New on_refresh_sort_columns parameter for DuckDB enables data ordering after writes
  • Improved Install Scripts: Removed jq dependency and improved cross-platform compatibility
  • Better Error Messages: Improved error messaging for bucket UDF arguments and deprecated OpenAI parameters
  • Reliability: Fixed DynamoDB IAM role authentication with new dynamodb_auth: iam_role parameter
  • Reliability: Fixed cluster executors to use scheduler's temp_directory parameter for shuffle files
  • Reliability: Initialize secrets before object stores in cluster executor mode
  • Reliability: Added page-level retry with backoff for transient GitHub GraphQL errors
  • Performance: Improved statistics for rewritten DistributeFileScanOptimizer plans
  • Developer Experience: Added max_message_size configuration for Flight service

Contributors​

Breaking Changes​

OTel Ingestion Port Change​

OTel ingestion has been moved to the Flight port (50051), removing the separate OTel port 50052. Port 50052 is now used exclusively for internal cluster communication. Update your configurations if you were using the dedicated OTel port.

Distributed Query Cluster Mode Requires mTLS​

Distributed query cluster mode now requires mTLS for secure communication between cluster nodes. This is a security enhancement to prevent unauthorized nodes from joining the cluster and accessing secrets.

Migration Steps:

  1. Generate certificates using spice cluster tls init and spice cluster tls add
  2. Update scheduler and executor startup commands with --node-mtls-* arguments
  3. For development/testing, use --allow-insecure-connections to opt out of mTLS

Renamed CLI Arguments:

Old NameNew Name
--cluster-mode--role
--cluster-ca-certificate-file--node-mtls-ca-certificate-file
--cluster-certificate-file--node-mtls-certificate-file
--cluster-key-file--node-mtls-key-file
--cluster-address--node-bind-address
--cluster-advertise-address--node-advertise-address
--cluster-scheduler-url--scheduler-address

Removed CLI Arguments:

  • --cluster-api-key: Replaced by mTLS authentication

Cookbook Updates​

New ScyllaDB Data Connector Recipe: New recipe demonstrating how to use the ScyllaDB Data Connector. See ScyllaDB Data Connector Recipe for details.

New SMB Data Connector Recipe: New recipe demonstrating how to use the SMB Data Connector. See SMB Data Connector Recipe for details.

The Spice Cookbook includes 86 recipes to help you get started with Spice quickly and easily.

Upgrading​

To upgrade to v1.11.0, use one of the following methods:

CLI:

spice upgrade

Homebrew:

brew upgrade spiceai/spiceai/spice

Docker:

Pull the spiceai/spiceai:1.11.0 image:

docker pull spiceai/spiceai:1.11.0

For available tags, see DockerHub.

Helm:

helm repo update
helm upgrade spiceai spiceai/spiceai --version 1.11.0

AWS Marketplace:

Spice is available in the AWS Marketplace.

Dependencies​

What's Changed​

Changelog​

Spice v1.11.0-rc.2 (Jan 22, 2026)

Β· 24 min read
Viktor Yershov
Member of Technical Staff at Spice AI

Announcing the release of Spice v1.11.0-rc.2! ⭐

v1.11.0-rc.2 is the second release candidate for advanced test of v1.11. It brings Spice Cayenne to Beta status with acceleration snapshots support, a new ScyllaDB Data Connector, upgrades to DataFusion v51, Arrow 57.2, and iceberg-rust v0.8.0. It includes significant improvements to distributed query, caching, and observability.

What's New in v1.11.0-rc.2​

Spice Cayenne Accelerator Reaches Beta​

Spice Cayenne has been promoted to Beta status with acceleration snapshots support and numerous stability improvements.

Improved Reliability:

  • Fixed timezone database issues in Docker images that caused acceleration panics
  • Resolved FuturesUnordered reentrant drop crashes
  • Fixed memory growth issues related to Vortex metrics allocation
  • Metadata catalog now properly respects cayenne_file_path location
  • Added warnings for unparseable configuration values

Example configuration with snapshots:

datasets:
- from: s3://my-bucket/data.parquet
name: my_dataset
acceleration:
enabled: true
engine: cayenne
mode: file

DataFusion v51 Upgrade​

Apache DataFusion has been upgraded to v51, bringing significant performance improvements, new SQL features, and enhanced observability.

DataFusion v51 ClickBench Performance

Performance Improvements:

  • Faster CASE Expression Evaluation: Expressions now short-circuit earlier, reuse partial results, and avoid unnecessary scattering, speeding up common ETL patterns
  • Better Defaults for Remote Parquet Reads: DataFusion now fetches the last 512KB of Parquet files by default, typically avoiding 2 I/O requests per file
  • Faster Parquet Metadata Parsing: Leverages Arrow 57's new thrift metadata parser for up to 4x faster metadata parsing

New SQL Features:

  • SQL Pipe Operators: Support for |> syntax for inline transforms
  • DESCRIBE <query>: Returns the schema of any query without executing it
  • Named Arguments in SQL Functions: PostgreSQL-style param => value syntax for scalar, aggregate, and window functions
  • Decimal32/Decimal64 Support: New Arrow types supported including aggregations like SUM, AVG, and MIN/MAX

Example pipe operator:

SELECT * FROM t
|> WHERE a > 10
|> ORDER BY b
|> LIMIT 5;

Improved Observability:

  • Improved EXPLAIN ANALYZE Metrics: New metrics including output_bytes, selectivity for filters, reduction_factor for aggregates, and detailed timing breakdowns

Arrow 57.2 Upgrade​

Spice has been upgraded to Apache Arrow Rust 57.2.0, bringing major performance improvements and new capabilities.

Arrow 57 Parquet Metadata Parsing Performance

Key Features:

  • 4x Faster Parquet Metadata Parsing: A rewritten thrift metadata parser delivers up to 4x faster metadata parsing, especially beneficial for low-latency use cases and files with large amounts of metadata
  • Parquet Variant Support: Experimental support for reading and writing the new Parquet Variant type for semi-structured data, including shredded variant values
  • Parquet Geometry Support: Read and write support for Parquet Geometry types (GEOMETRY and GEOGRAPHY) with GeospatialStatistics
  • New arrow-avro Crate: Efficient conversion between Apache Avro and Arrow RecordBatches with projection pushdown and vectorized execution support

iceberg-rust v0.8.0 Upgrade​

Spice has been upgraded to iceberg-rust v0.8.0, bringing improved Iceberg table support.

Key Features:

  • V3 Metadata Support: Full support for Iceberg V3 table metadata format
  • INSERT INTO Partitioned Tables: DataFusion integration now supports inserting data into partitioned Iceberg tables
  • Improved Delete File Handling: Better support for position and equality delete files, including shared delete file loading and caching
  • SQL Catalog Updates: Implement update_table and register_table for SQL catalog
  • S3 Tables Catalog: Implement update_table for S3 Tables catalog
  • Enhanced Arrow Integration: Convert Arrow schema to Iceberg schema with auto-assigned field IDs, _file column support, and Date32 type support

Acceleration Snapshots​

Acceleration snapshots enable point-in-time recovery and data versioning for accelerated datasets. Snapshots capture the state of accelerated data at specific points, allowing for fast bootstrap recovery and rollback capabilities.

Key Feature Improvements in v1.11:

  • Flexible Triggers: Configure when snapshots are created based on time intervals or stream batch counts
  • Automatic Compaction: Reduce storage overhead by compacting older snapshots (DuckDB only)
  • Bootstrap Integration: Snapshots can reset cache expiry on load for seamless recovery (DuckDB with Caching refresh mode)
  • Smart Creation Policies: Only create snapshots when data has actually changed

Example configuration:

datasets:
- from: s3://my-bucket/data.parquet
name: my_dataset
acceleration:
enabled: true
engine: cayenne
mode: file
snapshots: enabled
snapshots_trigger: time_interval
snapshots_trigger_threshold: 1h
snapshots_creation_policy: on_changed

Snapshots API and CLI: New API endpoints and CLI commands for managing snapshots programmatically. List, create, and restore snapshots directly from the command line or via HTTP.

For more details, refer to the Acceleration Snapshots Documentation.

ScyllaDB Data Connector​

A new data connector for ScyllaDB, the high-performance NoSQL database compatible with Apache Cassandra. Query ScyllaDB tables directly or accelerate them for faster analytics.

Example configuration:

datasets:
- from: scylladb:my_keyspace.my_table
name: scylla_data
acceleration:
enabled: true
engine: duckdb

For more details, refer to the ScyllaDB Data Connector Documentation.

Distributed Query Improvements​

mTLS Verification: Cluster communication between scheduler and executors now supports mutual TLS verification for enhanced security.

Credential Propagation: Azure and GCS credentials are now automatically propagated to executors in cluster mode, enabling access to cloud storage across the distributed query cluster.

Improved Resilience:

  • Exponential backoff for scheduler disconnection recovery
  • Increased gRPC message size limit from 16MB to 100MB for large query plans
  • HTTP health endpoint for cluster executors
  • Automatic executor role inference when --scheduler-address is provided

For more details, refer to the Distributed Query Documentation.

Caching Acceleration Mode Improvements​

The Caching Acceleration Mode introduced in v1.10.0 has received significant performance optimizations and reliability fixes in this release.

Performance Optimizations:

  • Non-blocking Cache Writes: Cache misses no longer block query responses. Data is written to the cache asynchronously after the query returns, reducing query latency for cache miss scenarios.
  • Batch Cache Writes: Multiple cache entries are now written in batches rather than individually, significantly improving write throughput for high-volume cache operations.

Reliability Fixes:

  • Correct SWR Refresh Behavior: The stale-while-revalidate (SWR) pattern now correctly refreshes only the specific entries that were accessed instead of refreshing all stale rows in the dataset. This prevents unnecessary source queries and reduces load on upstream data sources.
  • Deduplicated Refresh Requests: Fixed an issue where JSON array responses could trigger multiple redundant refresh operations. Refresh requests are now properly deduplicated.
  • Fixed Cache Hit Detection: Resolved an issue where queries that didn't include fetched_at in their projection would always result in cache misses, even when cached data was available.
  • Unfiltered Query Optimization: SELECT * queries without filters now return cached data directly without unnecessary filtering overhead.

For more details, refer to the Caching Acceleration Mode Documentation.

DynamoDB Connector Enhancements​

  • Added JSON nesting for DynamoDB Streams
  • Proper batch deletion handling

URL Tables​

Query data sources directly via URL in SQL without prior dataset registration. Supports S3, Azure Blob Storage, and HTTP/HTTPS URLs with automatic format detection and partition inference.

Supported Patterns:

  • Single files: SELECT * FROM 's3://bucket/data.parquet'
  • Directories/prefixes: SELECT * FROM 's3://bucket/data/'
  • Glob patterns: SELECT * FROM 's3://bucket/year=*/month=*/data.parquet'

Key Features:

  • Automatic file format detection (Parquet, CSV, JSON, etc.)
  • Hive-style partition inference with filter pushdown
  • Schema inference from files
  • Works with both SQL and DataFrame APIs

Example with hive partitioning:

-- Partitions are automatically inferred from paths
SELECT * FROM 's3://bucket/data/' WHERE year = '2024' AND month = '01'

Enable via spicepod.yml:

runtime:
params:
url_tables: enabled

Cluster Mode Async Query APIs (experimental)​

New asynchronous query APIs for long-running queries in cluster mode:

  • /v1/queries endpoint: Submit queries and retrieve results asynchronously
  • Arrow Flight async support: Non-blocking query execution via Arrow Flight protocol

Observability Improvements​

Enhanced Dashboards: Updated Grafana and Datadog example dashboards with:

  • Snapshot monitoring widgets
  • Improved accelerated datasets section
  • Renamed ingestion lag charts for clarity

Additional Histogram Buckets: Added more buckets to histogram metrics for better latency distribution visibility.

For more details, refer to the Monitoring Documentation.

Additional Improvements​

  • Model Listing: New functionality to list available models across multiple AI providers
  • DuckDB Partitioned Tables: Primary key constraints now supported in partitioned DuckDB table mode
  • Post-refresh Sorting: New on_refresh_sort_columns parameter for DuckDB enables data ordering after writes
  • Improved Install Scripts: Removed jq dependency and improved cross-platform compatibility
  • Better Error Messages: Improved error messaging for bucket UDF arguments and deprecated OpenAI parameters

Contributors​

Breaking Changes​

No breaking changes.

Cookbook Updates​

New ScyllaDB Data Connector Recipe: New recipe demonstrating how to use ScyllaDB Data Connector. See ScyllaDB Data Connector Recipe for details.

New SMB Data Connector Recipe: New recipe demonstrating how to use ScyllaDB Data Connector. See SMB Data Connector Recipe for details.

The Spice Cookbook includes 86 recipes to help you get started with Spice quickly and easily.

Upgrading​

To upgrade to v1.11.0-rc.2, use one of the following methods:

CLI:

spice upgrade

Homebrew:

brew upgrade spiceai/spiceai/spice

Docker:

Pull the spiceai/spiceai:v1.11.0-rc.2 image:

docker pull spiceai/spiceai:v1.11.0-rc.2

For available tags, see DockerHub.

Helm:

helm repo update
helm upgrade spiceai spiceai/spiceai

AWS Marketplace:

Spice is available in the AWS Marketplace.

Dependencies​

Changelog​

Spice v1.10.2 (Dec 22, 2025)

Β· 5 min read
Sergei Grebnov
Member of Technical Staff at Spice AI

Announcing the release of Spice v1.10.2! πŸ”₯

v1.10.2 introduces Tiered Caching Acceleration with Localpod for multi-layer acceleration architectures, Periodic Acceleration Snapshots with configurable intervals, DynamoDB JSON Nesting for column consolidation, and Kafka/Debezium Batching for faster data ingestion. This release also includes fixes for SQLite accelerator decimal/date handling and real-time status reporting for the /v1/datasets and /v1/models API endpoints.

What's New in v1.10.2​

Tiered Caching with Localpod​

Multi-Layer Acceleration Architecture: The Localpod connector now supports caching refresh mode, enabling tiered acceleration where a persistent cache (e.g., file-mode DuckDB) feeds a fast in-memory cache (e.g., Arrow, memory-mode DuckDB).

Key Features:

  • Automatic Cache Propagation: New cache entries automatically propagate from parent to child accelerators
  • Warm Startup: Child accelerators initialize from existing parent data on startup, eliminating cold-start latency
  • Flexible Tiering: Combine any accelerator engines (DuckDB, SQLite, Cayenne) across tiers

Example spicepod.yaml configuration:

datasets:
# Parent: persistent file-mode cache
- from: https://api.example.com
name: api_cache
acceleration:
enabled: true
refresh_mode: caching
engine: duckdb
mode: file

# Child: fast in-memory cache fed by parent
- from: localpod:api_cache
name: api_cache_memory
acceleration:
enabled: true
refresh_mode: caching
engine: arrow
mode: memory

For more details, refer to the Localpod Data Connector Documentation.

Periodic Acceleration Snapshots​

Configurable Snapshot Intervals: A new snapshots_create_interval parameter enables periodic snapshot creation for accelerated datasets across all refresh modes. This provides better control over snapshot frequency and ensures consistent recovery points for accelerated data.

Example spicepod.yaml configuration:

datasets:
- from: s3://my-bucket/data.parquet
name: my_data
acceleration:
enabled: true
engine: duckdb
mode: file
refresh_mode: caching
snapshots: enabled
params:
snapshots_create_interval: 60s # Write a snapshot every 60 seconds

For more details, refer to the Data Acceleration Documentation.

DynamoDB JSON Nesting​

Consolidate Columns into JSON: The DynamoDB Data Connector now supports consolidating columns into a single JSON column using the json_object: "*" metadata option. This is useful when only a few columns are needed as discrete fields while the rest can be accessed as nested JSON.

Example spicepod.yaml configuration:

datasets:
- from: dynamodb:my_table
name: my_table
columns:
- name: PK
- name: SK
- name: data_json
metadata:
json_object: '*' # Captures all other columns as JSON

Example Output: Given a DynamoDB table with columns PK, SK, name, email, and status, the resulting table schema consolidates all non-specified columns into the data_json column:

PKSKdata_json
pk_1sort_1{"name": "Alice", "email": "[email protected]", "status": "active"}
pk_2sort_2{"name": "Bob", "email": "[email protected]", "status": "inactive"}

For more details, refer to the DynamoDB JSON Nesting Documentation.

Kafka/Debezium Batching​

Faster Data Ingestion: Configure message batching for Kafka and Debezium connectors to improve data ingestion throughput. Batching reduces processing overhead by grouping multiple messages together before insertion.

Key Features:

  • Configurable Batch Size: Control the maximum number of records per batch (default: 10,000)
  • Configurable Batch Duration: Set the maximum wait time before flushing a partial batch (default: 1s)

Example spicepod.yaml configuration:

datasets:
- from: debezium:kafka-server.public.my_table
name: my_table
params:
batch_max_size: 10000 # Max records per batch (default: 10000)
batch_max_duration: 1s # Max wait time per batch (default: 1s)

For more details, refer to the Kafka Data Connector Documentation and Debezium Data Connector Documentation.

Additional Improvements & Bug Fixes​

  • Reliability: Fixed SQLite accelerator decimal and date type handling for improved data type accuracy.
  • Reliability: Fixed real-time status reporting for /v1/datasets and /v1/models API endpoints.
  • Reliability: Fixed Kafka warning when security.protocol is set to PLAINTEXT.

Contributors​

Breaking Changes​

No breaking changes.

Cookbook Updates​

New Cayenne Data Accelerator Recipe: New recipe demonstrating how to accelerate a local copy of the taxi trips dataset using Cayenne as the data accelerator engine. See Cayenne Data Accelerator Recipe for details.

New Dataset Partitioning Recipe: New recipe demonstrating how to partition accelerated datasets to improve query performance. See Dataset Partitioning for details.

The Spice Cookbook includes 84 recipes to help you get started with Spice quickly and easily.

Upgrading​

To upgrade to v1.10.2, use one of the following methods:

CLI:

spice upgrade

Homebrew:

brew upgrade spiceai/spiceai/spice

Docker:

Pull the spiceai/spiceai:1.10.2 image:

docker pull spiceai/spiceai:1.10.2

For available tags, see DockerHub.

Helm:

helm repo update
helm upgrade spiceai spiceai/spiceai

AWS Marketplace:

πŸŽ‰ Spice is now available in the AWS Marketplace!

What's Changed​

Changelog​

Spice v1.8.1 (Oct 13, 2025)

Β· 5 min read
Viktor Yershov
Member of Technical Staff at Spice AI

Announcing the release of Spice v1.8.1! πŸš€

Spice v1.8.1 is a patch release that adds Acceleration Snapshots Indexes, and includes a number of bug fixes and performance improvements.

What's New in v1.8.1​

Acceleration Snapshot Indexes​

  • Management of Acceleration Snapshots has been improved by adopting an Iceberg-inspired metadata.json, which now encodes pointer IDs, schema serialization, and robust checksum and size, which is validate before loading the snapshot.

  • Acceleration Snapshot Metrics: The following metrics are now available for Acceleration Snapshots:

  • dataset_acceleration_snapshot_bootstrap_duration_ms: The time it took the runtime to download the snapshot - only emitted when it initially downloads the snapshot.

  • dataset_acceleration_snapshot_bootstrap_bytes: The number of bytes downloaded to bootstrap the acceleration from the snapshot.

  • dataset_acceleration_snapshot_bootstrap_checksum: The checksum of the snapshot used to bootstrap the acceleration.

  • dataset_acceleration_snapshot_failure_count: Number of failures encountered when writing a new snapshot at the end of the refresh cycle. A snapshot failure does not prevent the refresh from completing.

  • dataset_acceleration_snapshot_write_timestamp: Unix timestamp in seconds when the last snapshot was completed.

  • dataset_acceleration_snapshot_write_duration_ms: The time it took to write the snapshot to object storage.

  • dataset_acceleration_snapshot_write_bytes: The number of bytes written on the last snapshot write.

  • dataset_acceleration_snapshot_write_checksum: The SHA256 checksum of the last snapshot write.

To learn more, see the Acceleration Snapshots Documentation and the Metrics Documentation.

Improved Regular Expression for DuckDB acceleration​

Regular expression support has been expanded when using DuckDB acceleration for functions like regexp-like and regexp_match.

For more details, refer to the SQL Reference for the list of available regular expression functions.

Additional Improvements & Bugfixes​

  • Reliability: Resolved an issue with partitioning on empty partition sets.
  • Validation: Added better validation for incorrectly configured Spicepods.
  • Reliability: Fixed partition_by accelerations when a projection is applied on empty partition sets.
  • Performance: Ensured ListingTable partitions are pruned when filters are not used.
  • Performance: Don't download acceleration snapshots if the acceleration is already present.
  • Performance: Refactored some blocking I/O and synchronization in the async codebase by moving operations to tokio::task::spawn_blocking, replacing blocking locks with async-friendly variants.
  • Bugfix: Nullable fields are now supported for S3 Vectors index columns.

Contributors​

Breaking Changes​

No breaking changes.

Cookbook Updates​

  • New Accelerated Snapshots Recipe - The recipe shows how to bootstrap DuckDB accelerations from object storage to skip cold starts.

The Spice Cookbook includes 81 recipes to help you get started with Spice quickly and easily.


Upgrading​

To upgrade to v1.8.1, use one of the following methods:

CLI:

spice upgrade

Homebrew:

brew upgrade spiceai/spiceai/spice

Docker:

Pull the spiceai/spiceai:1.8.1 image:

docker pull spiceai/spiceai:1.8.1

For available tags, see DockerHub.

Helm:

helm repo update
helm upgrade spiceai spiceai/spiceai

AWS Marketplace:

πŸŽ‰ Spice is now available in the AWS Marketplace!

What's Changed​

Changelog​

Spice v1.8.0 (Oct 6, 2025)

Β· 20 min read
Phillip LeBlanc
Co-Founder and CTO of Spice AI

Announcing the release of Spice v1.8.0! 🧊

Spice v1.8.0 delivers major advances in data writes, scalable vector search, and now in previewβ€”managed acceleration snapshots for fast cold starts. This release introduces write support for Iceberg tables using standard SQL INSERT INTO, partitioned S3 Vector indexes for petabyte-scale vector search, and preview of the AI SQL function for direct LLM integration in SQL. Additional improvements include improved reliability, and the v3.0.3 release of the Spice.js Node.js SDK.

What's New in v1.8.0​

Iceberg Table Write Support (Preview)​

Append Data to Iceberg Tables with SQL INSERT INTO: Spice now supports writing to Iceberg tables and catalogs using standard SQL INSERT INTO statements. This enables data ingestion, transformation, and pipeline use casesβ€”no Spark or external writer required.

  • Append-only: Initial version targets appends; no overwrite or delete.
  • Schema validation: Inserted data must match the target table schema.
  • Secure by default: Writes are only enabled for datasets or catalogs explicitly marked with access: read_write.

Example Spicepod configuration:

catalogs:
- from: iceberg:https://glue.ap-northeast-3.amazonaws.com/iceberg/v1/catalogs/111111/namespaces
name: ice
access: read_write

datasets:
- from: iceberg:https://iceberg-catalog-host.com/v1/namespaces/my_namespace/tables/my_table
name: iceberg_table
access: read_write

Example SQL usage:

-- Insert from another table
INSERT INTO iceberg_table
SELECT * FROM existing_table;

-- Insert with values
INSERT INTO iceberg_table (id, name, amount)
VALUES (1, 'John', 100.0), (2, 'Jane', 200.0);

-- Insert into catalog table
INSERT INTO ice.sales.transactions
VALUES (1001, '2025-01-15', 299.99, 'completed');

Note: Only Iceberg datasets and catalogs with access: read_write support writes. Internal Spice tables and other connectors remain read-only.

Learn more in the Iceberg Data Connector documentation.

Acceleration Snapshots for Fast Cold Starts (Preview)​

Bootstrap Managed Accelerations from Object Storage: Spice now supports managed acceleration snapshots in preview, enabling datasets accelerated with file-based engines (DuckDB or SQLite) to bootstrap from a snapshot stored in object storage (such as S3) if the local acceleration file does not exist on startup. This dramatically reduces cold start times and enables ephemeral storage for accelerations with persistent recovery.

Key features:

  • Rapid readiness: Datasets can become ready in seconds by downloading a pre-built snapshot, skipping lengthy initial acceleration.
  • Hive-style partitioning: Snapshots are organized by month, day, and dataset for easy retention and management.
  • Flexible bootstrapping: Configurable fallback and retry behavior if a snapshot is missing or corrupted.

Example Spicepod configuration:

snapshots:
enabled: true
location: s3://some_bucket/some_folder/ # Folder for storing snapshots
bootstrap_on_failure_behavior: warn # Options: warn, retry, fallback
params:
s3_auth: iam_role # All S3 dataset params accepted here

datasets:
- from: s3://some_bucket/some_table/
name: some_table
params:
file_format: parquet
s3_auth: iam_role
acceleration:
enabled: true
snapshots: enabled # Options: enabled, disabled, bootstrap_only, create_only
engine: duckdb
mode: file
params:
duckdb_file: /nvme/some_table.db

How it works:

  • On startup, if the acceleration file does not exist, Spice checks the snapshot location for the latest snapshot and downloads it.
  • Snapshots are stored as: s3://some_bucket/some_folder/month=2025-09/day=2025-09-30/dataset=some_table/some_table_<timestamp>.db
  • If no snapshot is found, a new acceleration file is created as usual.
  • Snapshots are written after each refresh (unless configured otherwise).

Supported snapshot modes:

  • enabled: Download and write snapshots.
  • bootstrap_only: Only download on startup, do not write new snapshots.
  • create_only: Only write snapshots, do not download on startup.
  • disabled: No snapshotting.

Note: This feature is only supported for file-based accelerations (DuckDB or SQLite) with dedicated files.

Why use acceleration snapshots?

  • Faster cold starts: Skip waiting for full acceleration on startup.
  • Ephemeral storage: Use fast local disks (e.g., NVMe) for acceleration, with persistent recovery from object storage.
  • Disaster recovery: Recover from federated source outages by bootstrapping from the latest snapshot.

Partitioned S3 Vector Indexes​

Efficient, Scalable Vector Search with Partitioning: Spice now supports partitioning Amazon S3 Vector indexes and scatter-gather queries using a partition_by expression in the dataset vector engine configuration. Partitioned indexes enable faster ingestion, lower query latency, and scale to billions of vectors.

Example Spicepod configuration:

datasets:
- name: reviews
vectors:
enabled: true
engine: s3_vectors
params:
s3_vectors_bucket: my-bucket
s3_vectors_index: base-embeddings
partition_by:
- 'bucket(50, PULocationID)'
columns:
- name: body
embeddings:
from: bedrock_titan
- name: title
embeddings:
from: bedrock_titan

See the Amazon S3 Vectors documentation for details.

AI SQL function for LLM Integration (Preview)​

LLMs Directly In SQL: A new asynchronous ai SQL function enables direct calls to LLMs from SQL queries for text generation, translation, classification, and more. This feature is released in preview and supports both default and model-specific invocation.

Example Spicepod model configuration:

models:
- name: gpt-4o
from: openai:gpt-4o
params:
openai_api_key: ${secrets:openai_key}

Example SQL usage:

-- basic usage with default model
SELECT ai('hi, this prompt is directly from SQL.');
-- basic usage with specified model
SELECT ai('hi, this prompt is directly from SQL.', 'gpt-4o');
-- Using row data as input to the prompt
SELECT ai(concat_ws(' ', 'Categorize the zone', Zone, 'in a single word. Only return the word.')) AS category
FROM taxi_zones
LIMIT 10;

Learn more in the SQL Reference AI documentation.

Remote Endpoint Support for Spice CLI​

Run CLI Commands Remotely: The Spice CLI now supports connecting to remote Spice instances, enabling you to run spice sql, spice search, and spice chat commands from your local machine against a remote spiced daemon or to Spice Cloud. Previously, these commands required running on the same machine as the runtime. Now, new flags allow remote execution:

  • --cloud: Connect to a Spice Cloud instance (requires --api-key).
  • --endpoint <endpoint>: Connect to a remote Spice instance via HTTP or Arrow Flight SQL (gRPC). Supports http://, https://, grpc://, or grpc+tls:// schemes.

Examples:

# Run SQL queries against a remote Spice instance
spice sql --endpoint http://remote-host:8090

# Use Spice Cloud for chat or search
spice chat --cloud --api-key <your-api-key>
spice search --cloud --api-key <your-api-key>

Supported CLI Commands:

  • spice sql --cloud / spice sql --endpoint <endpoint>
  • spice search --cloud / spice search --endpoint <endpoint>
  • spice chat --cloud / spice chat --endpoint <endpoint>

Additional Flags:

  • --headers: Pass custom HTTP headers to the remote endpoint.
  • --tls-root-certificate-file: Specify a root certificate for TLS verification.
  • --user-agent: Set a custom user agent for requests.

For more details, see the Spice CLI Command Reference.

Spice.js v3.0.3 SDK​

Spice.js v3.0.3 Released: The official Spice.ai Node.js/JavaScript SDK has been updated to v3.0.3, bringing cross-platform support, new APIs, and improved reliability for both Node.js and browser environments.

  • Modern Query Methods: Use sql(), sqlJson(), and nsql() for flexible querying, streaming, and natural language to SQL.
  • Browser Support: SDK now works in browsers and web applications, automatically selecting the optimal transport (gRPC or HTTP).
  • Health Checks & Dataset Refresh: Easily monitor Spice runtime health and trigger dataset refreshes on demand.
  • Automatic HTTP Fallback: If gRPC/Flight is unavailable, the SDK falls back to HTTP automatically.
  • Migration Guidance: v3 requires Node.js 20+, uses camelCase parameters, and introduces a new package structure.

Example usage:

import { SpiceClient } from '@spiceai/spice'

const client = new SpiceClient(apiKey)
const table = await client.sql('SELECT * FROM my_table LIMIT 10')
console.table(table.toArray())

See Spice.js SDK documentation for full details, migration tips, and advanced usage.

Additional Improvements​

  • Reliability: Improved logging, error handling, and network readiness checks across connectors (Iceberg, Databricks, etc.).
  • Vector search durability and scale: Refined logging, stricter default limits, safeguards against index-only scans and duplicate results, and always-accessible metadata for robust queryability at scale.
  • Cache behavior: Tightened cache logic for modification queries.
  • Full-Text Search: FTS metadata columns now usable in projections; max search results increased to 1000.
  • RRF Hybrid Search: Reciprocal Rank Fusion (RRF) UDTF enhancements for advanced hybrid search scenarios.

Contributors​

Breaking Changes​

This release introduces two breaking changes associated with the search observability and tooling.

Firstly, the document_similarity tool has been renamed to search. This has the equivalent change to tracing of these tool calls:

## Old: v1.7.1
>> spice trace tool_use::document_similarity
>> curl -XPOST http://localhost:8090/v1/tools/document_similarity \
-d '{
"datasets": ["my_tbl"],
"text": "Welcome to another Spice release"
}'

## New: v1.8.0
>> spice trace tool_use::search
>> curl -XPOST http://localhost:8090/v1/tools/search \
-d '{
"datasets": ["my_tbl"],
"text": "Welcome to another Spice release"
}'

Secondly, the vector_search task in runtime.task_history has been renamed to search.

Cookbook Updates​

The Spice Cookbook now includes 80 recipes to help you get started with Spice quickly and easily.


Upgrading​

To upgrade to v1.8.0, use one of the following methods:

CLI:

spice upgrade

Homebrew:

brew upgrade spiceai/spiceai/spice

Docker:

Pull the spiceai/spiceai:1.8.0 image:

docker pull spiceai/spiceai:1.8.0

For available tags, see DockerHub.

Helm:

helm repo update
helm upgrade spiceai spiceai/spiceai

AWS Marketplace:

πŸŽ‰ Spice is now available in the AWS Marketplace!

What's Changed​

Dependencies​

  • iceberg-rust: Upgraded to v0.7.0-rc.1
  • mimalloc: Upgraded from 0.1.47 to 0.1.48
  • azure_core: Upgraded from 0.27.0 to 0.28.0
  • Jimver/cuda-toolkit: Upgraded from 0.2.27 to 0.2.28

Changelog​